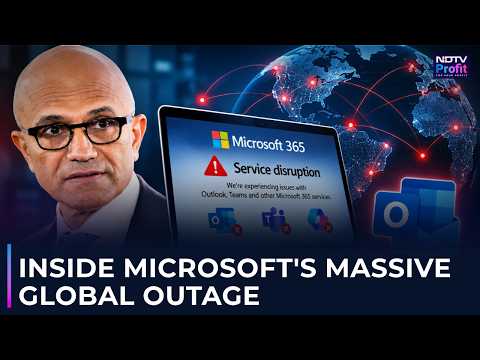
A major Microsoft global outage has triggered widespread disruption, affecting businesses, government agencies, healthcare organizations and millions of everyday users. Popular services, including Outlook, Microsoft Teams and Microsoft 365, have experienced connectivity problems as the technology giant struggles to restore normal operations.
The disruption began on Thursday, November 12, 2026, and continued into Friday, November 13. What initially appeared to be a service problem in parts of Microsoft’s infrastructure quickly developed into a worldwide technology crisis.
Users across multiple countries reported difficulties accessing their email accounts, opening online documents and communicating through workplace applications. For organizations that depend heavily on Microsoft’s cloud-based services, the disruption created serious operational challenges.
Microsoft has acknowledged the problems and launched recovery efforts. However, restoring affected systems has proved more complicated than expected.
The company has also said that it is not currently aware of malicious activity causing the incident. Instead, its investigation has focused on server availability, infrastructure configuration and traffic-management problems.
The Guardian+2
What Happened During the Microsoft Outage?
The disruption started around November 12, when users began reporting problems with Outlook and other Microsoft services.
Initially, the company investigated connectivity issues affecting parts of its infrastructure. However, reports quickly spread across different regions, indicating that the incident was not limited to one country or a small group of customers.
Microsoft later identified unexpected server unavailability and elevated infrastructure loads as major factors behind the disruption.
The situation became more complicated when some servers that had been brought back online became unresponsive again as traffic returned.
This created additional pressure on Microsoft’s recovery teams. Restoring a server is only one part of the process. The company must also ensure that the infrastructure can handle normal customer demand without experiencing another failure.
According to Microsoft’s service updates, its initial recovery efforts were not progressing as expected. The company therefore began exploring alternative ways to restore capacity and stabilize affected systems.
The outage demonstrated how quickly a technical problem inside a major cloud platform can spread across industries and international markets.
The Guardian+2
Which Microsoft Services Were Affected?
The outage affected several widely used Microsoft products. However, the impact was not identical across every application or region.
Some services experienced serious access problems, while certain features continued working normally.
The main affected services included:
1. Microsoft Outlook
Outlook became one of the most visibly affected services during the incident.
Users reported problems opening inboxes, sending messages and receiving emails. Some customers also experienced delayed message delivery.
This created significant problems for companies that use Outlook as their primary communication platform.
For many businesses, email is essential for customer support, internal coordination, financial approvals and daily operations. Even temporary access problems can create substantial backlogs.
2. Microsoft Teams
Microsoft Teams also experienced disruption.
The platform is widely used for workplace meetings, group communication and collaboration. However, Microsoft indicated that not every Teams feature was equally affected.
Core functions such as joining meetings, group chats and channel messages were reported to remain available in some circumstances.
Calendar-related activities, including scheduling and viewing meetings, experienced problems.
This distinction is important because the outage did not necessarily make every Microsoft application completely unavailable.
3. Microsoft 365
Microsoft 365 users also faced difficulties accessing cloud-based workplace services.
The disruption particularly affected features connected to Exchange Online, Microsoft’s cloud-based email platform.
Organizations relying on Microsoft 365 for documents, communication and business administration experienced interruptions.
4. OneDrive and OneNote
Microsoft’s consumer service updates also identified OneDrive and OneNote among the products experiencing access problems.
These applications are important for storing files, synchronizing information and managing digital notes.
Users who depend on cloud storage may have experienced difficulties accessing their information or completing normal tasks.
5. Microsoft Copilot
Microsoft Copilot also experienced disruption during the incident.
The AI assistant relies on Microsoft’s wider infrastructure and, in workplace environments, can connect with organizational information.
Users reported problems loading Copilot Chat or receiving responses through certain applications.
The disruption highlighted another important issue: AI services are not independent of the cloud infrastructure supporting them.
Moneycontrol+2
Global Ripple Effects: Businesses and Governments Face Disruption
The Microsoft outage became more than an inconvenience for individual users. Its consequences spread into important public and private sector operations.
Organizations across different countries rely on Microsoft’s cloud ecosystem to manage communication, documents, internal systems and customer services.
When those services become unavailable, the effects can extend far beyond the original technical problem.
Government Agencies Face Operational Challenges
Government departments are among the organizations that depend heavily on digital communication systems.
During this incident, government agencies in several countries reported disruption.
Australia experienced problems affecting public services, including government operations and security-related organizations.
Japan also reported significant concerns. The country’s economy, trade and industry minister described the disruption as having a major impact.
Government organizations in other regions also monitored the situation and prepared contingency arrangements.
The incident demonstrated why public institutions need alternative communication systems when major technology providers experience unexpected failures.
The Guardian+2
Healthcare Services Experience Communication Problems
Healthcare organizations also reported difficulties linked to the Microsoft outage.
In the United Kingdom, NHS-related organizations reported problems involving Outlook and Teams.
Some healthcare providers warned patients that emails might not be received and advised them to use telephone communication instead.
This distinction matters because healthcare services cannot simply stop operating whenever a technology platform experiences problems.
Hospitals, clinics and medical professionals must continue coordinating appointments, patient communication and administrative responsibilities.
Although the outage did not mean that all healthcare systems stopped functioning, it exposed the importance of maintaining reliable backup communication channels.
Police and Public Services Face Additional Pressure
Police organizations also reported problems.
In the United Kingdom, some forces experienced difficulties receiving online crime reports because of Microsoft-related service disruptions.
Authorities encouraged people to use alternative contact methods when online reporting systems were unavailable.
This situation demonstrated how a cloud service interruption can affect public-facing services that citizens normally expect to operate continuously.
Schools and Educational Institutions Struggle
Educational institutions also faced challenges.
Schools and universities increasingly use cloud-based platforms for communication, administration, online learning and document management.
When email and collaboration services become unreliable, teachers, administrators, students and parents can experience delays.
Some schools advised people to use telephone communication instead of relying on email.
For educational institutions with limited alternative systems, even a short outage can disrupt everyday administrative activities.
The Guardian+2
India Also Feels the Impact of the Microsoft Outage
India was among the countries where users reported problems accessing Microsoft services.
Reports of disruption began appearing on November 12, with complaints increasing again during the morning of November 13.
Indian businesses, professionals and ordinary users rely heavily on Outlook, Teams and Microsoft 365 for daily activities.
The outage therefore created difficulties for people who depend on these applications for professional communication.
One notable example involved IndiGo, which reported that its email support services were affected by the global Microsoft disruption.
The airline said customers might experience problems when contacting it through email. However, it advised customers needing urgent assistance to use other available support channels, including its website and mobile application.
The airline’s update illustrated how a problem affecting an external technology provider can create customer-service challenges for an organization that does not directly control the affected infrastructure.
For Indian companies, the incident also raised questions about cloud dependency, business continuity and alternative communication arrangements.
The Economic Times+2
What Caused the Microsoft Global Outage?
The exact root cause had not been fully established in the available updates on November 13.
However, Microsoft provided information about the infrastructure problems affecting its services.
The company said that a number of servers had become unexpectedly unavailable.
It also explained that elevated infrastructure load across multiple regions was contributing to connectivity problems.
Importantly, Microsoft indicated that the increased load was not simply the result of a sudden increase in customer traffic.
Instead, the unavailability of servers created pressure on the remaining infrastructure.
Server Availability Problems
Large cloud platforms depend on thousands of interconnected systems.
These systems distribute customer requests across different servers and infrastructure locations.
When some servers become unavailable, other systems may need to handle additional workloads.
This can create pressure across the wider network.
In Microsoft’s case, the recovery process became complicated because some servers reportedly became unresponsive again after traffic was redirected toward them.
Configuration and Routing Issues
Microsoft’s recovery updates also referred to an upstream authentication and routing configuration component.
The company reported applying a patch to part of its infrastructure to improve server stability.
Authentication systems help verify users and allow them to access services. Routing systems help direct requests to the appropriate infrastructure.
Problems involving these components can affect connectivity even when individual applications have not experienced a separate software failure.
However, the exact technical sequence behind the incident remained subject to Microsoft’s investigation.
Recovery Efforts Become More Complicated
Microsoft initially attempted to restore affected infrastructure through its regular recovery processes.
However, the company acknowledged that some recovery actions were not working as expected.
It then explored alternative approaches to improve capacity and manage traffic.
The company also began monitoring server performance and gradually restoring affected workloads.
These developments explain why the outage continued for so long despite Microsoft’s efforts to resolve it.
Al Jazeera+2
Microsoft Says There Is No Indication of a Cyberattack
One of the major concerns during any large technology outage is whether hackers or malicious actors are responsible.
A disruption affecting multiple countries and essential services can naturally raise cybersecurity questions.
However, Microsoft said it was not aware of malicious activity causing the incident.
The company’s updates indicated that its investigation was focused on technical infrastructure problems rather than a confirmed cyberattack.
Australian officials also reported that Microsoft believed the situation involved a technical issue rather than a malicious intrusion.
This distinction is important.
A major outage does not automatically mean that a company has been hacked. Technical failures, configuration problems, software updates and infrastructure instability can also produce widespread disruption.
Nevertheless, organizations must continue monitoring cybersecurity risks during service interruptions.
Attackers sometimes attempt to exploit confusion surrounding major outages through fake support messages, fraudulent websites and phishing emails.
Users should therefore remain cautious about unexpected messages claiming to offer emergency Microsoft account recovery.
Microsoft has indicated that it will provide a fuller explanation after the incident is mitigated and its investigation is complete.
The Guardian+2
Microsoft Begins Recovery as Outage Enters Its Second Day
By Friday, November 13, Microsoft had reported progress in its efforts to restore affected services.
The company said it was seeing positive results for server stability after applying a patch to part of its infrastructure.
However, the situation remained far from completely resolved.
Microsoft warned that service capacity had not returned to normal levels and that performance continued to vary across affected systems.
The company began gradually reintroducing traffic while monitoring server performance.
It also worked on improving email delivery and protecting delayed messages.
One important recovery measure involved extending the email timeout window to 48 hours. This was intended to help protect delayed messages while restoration efforts continued.
The company also reported incremental improvements in mailbox access and email processing.
However, users could still experience intermittent problems.
There was no confirmed timetable for complete restoration in the updates available at the time.
This meant that businesses and individuals still needed to prepare for possible delays.
ITV News+2
Financial Markets and Businesses Face Wider Consequences
The Microsoft outage also demonstrated how technology failures can create financial consequences.
Modern businesses depend on digital communication for transactions, customer relationships and operational decisions.
When email systems become unreliable, even routine activities can become slower.
Financial professionals, for example, may use email to receive confirmations, communicate with clients and coordinate trading activities.
During the outage, some financial market participants reported difficulties accessing emails and receiving transaction confirmations.
Some organizations turned to telephone calls and messaging applications to maintain communication.
This shift may appear simple, but it can increase operational pressure when hundreds or thousands of employees suddenly need alternative communication channels.
For international companies, the situation can become even more complicated because different offices operate across multiple time zones.
The longer a disruption continues, the greater the potential for delayed decisions, missed communications and administrative backlogs.
The incident also highlighted the importance of evaluating the financial risks associated with relying heavily on one technology provider.
The Guardian+2
Why the Microsoft Outage Raises Questions About Cloud Dependency
Cloud computing has transformed the way organizations operate.
Instead of maintaining every server and application themselves, businesses can purchase services from major technology providers.
Microsoft has become a central part of this digital ecosystem through Microsoft 365, Azure-related infrastructure and workplace applications.
This approach offers several advantages.
Companies can access tools from different locations, collaborate remotely and reduce the need to maintain extensive local infrastructure.
However, the global outage exposed a significant weakness.
When an important cloud provider experiences a major disruption, many organizations can face problems simultaneously.
This creates a concentration risk.
A company may have excellent internal systems, trained employees and reliable internet access. Yet, if its essential cloud services become unavailable, its operations can still suffer.
The problem is particularly serious when several departments depend on the same platform.
For example:
Human resources may rely on Outlook for employee communication.
Finance teams may use Microsoft 365 for documents and reporting.
Sales departments may depend on email for customer communication.
Managers may use Teams for meetings.
IT departments may rely on cloud-based administration tools.
A single infrastructure incident can therefore affect multiple business functions at the same time.
The November outage has renewed the debate about digital resilience and whether organizations should maintain alternative systems for essential operations.
What Can Businesses Do to Avoid Similar Disruptions?
The Microsoft incident offers important lessons for companies that depend on cloud-based technology.
Although organizations cannot prevent every external service failure, they can reduce the damage through better preparation.
1. Maintain Alternative Communication Channels
Businesses should avoid depending entirely on one email platform.
Emergency telephone numbers, approved messaging applications and backup communication arrangements can help employees stay connected.
These alternatives should be tested before an outage occurs.
2. Create Reliable Data Backups
Important documents and business records should have appropriate backup arrangements.
Organizations should understand which information is stored in cloud platforms and how they can access essential records during a service interruption.
3. Develop a Business Continuity Plan
A business continuity plan explains how an organization will operate when important systems become unavailable.
It should identify critical services, responsible employees and alternative working procedures.
Companies should also conduct regular recovery exercises.
4. Review Cloud Provider Dependencies
Organizations should understand how many essential business functions depend on one technology provider.
Where practical, they should consider alternative systems for critical operations.
This does not necessarily mean abandoning Microsoft products. It means ensuring that a single provider’s outage cannot completely stop essential business activities.
5. Communicate Clearly With Customers
Businesses should prepare alternative customer-support channels.
If email becomes unavailable, customers should know how to reach the company through telephone support, websites or other approved communication methods.
The IndiGo response during the November disruption provides an example of why alternative support arrangements matter.
Could Another Major Technology Outage Happen?
Unfortunately, no large technology platform can guarantee uninterrupted service forever.
Modern digital infrastructure is complex. It includes servers, networking equipment, authentication systems, software configurations and interconnected cloud services.
Failures can occur even when companies invest heavily in reliability and cybersecurity.
The Microsoft incident also highlights an important difference between local failures and global disruptions.
A local problem may affect a limited number of customers. However, a problem involving shared infrastructure can spread across multiple services and geographical regions.
The more organizations depend on interconnected platforms, the more important resilience becomes.
Technology companies must continue investing in monitoring, infrastructure testing and recovery systems.
Customers, meanwhile, should evaluate whether their own operations can continue during an extended service interruption.
The goal should not simply be preventing outages. It should also be limiting their consequences.
What Happens Next for Microsoft?
Microsoft’s immediate priority remains restoring normal service across affected infrastructure.
The company has reported encouraging improvements following its recovery actions, but it must ensure that restored systems remain stable as customer traffic increases.
The next important step will be understanding exactly why the infrastructure became unstable.
A comprehensive post-incident report should help explain the root cause, the recovery process and the preventive measures Microsoft plans to introduce.
Customers will also want answers about how the incident affected service reliability and what changes will reduce the risk of similar disruptions.
For businesses, the incident may influence future decisions about cloud contracts, backup arrangements and technology diversification.
For individual users, the most immediate concern is simpler: when will their email, documents and collaboration tools work normally again?
Until Microsoft confirms full recovery, customers should continue checking official service updates and use alternative communication methods when necessary.
Conclusion: Microsoft Outage Exposes the Risks of a Connected World
The Microsoft global outage has become a major reminder of how dependent modern society is on cloud-based technology.
What began as a technical infrastructure problem quickly affected communication, business operations and public services across multiple countries.
Outlook, Teams and other Microsoft 365 services experienced disruption, while government agencies, healthcare organizations, financial professionals and businesses faced operational challenges.
Microsoft has reported progress in restoring server stability and improving service capacity. However, intermittent problems remained during the latest available updates on November 13.
The company has also said it is not aware of malicious activity behind the incident.
Ultimately, the outage raises a bigger question about digital dependency.
Cloud computing provides enormous benefits, but organizations must prepare for the possibility that even major technology providers can experience serious failures.
The real lesson is clear: reliable digital services require more than powerful infrastructure. They also require effective backup systems, transparent communication and strong recovery planning.
As Microsoft works to restore normal operations, businesses worldwide will be watching closely.
The incident could become an important turning point in how organizations approach cloud reliability and digital resilience.
Frequently Asked Questions (FAQs)
1. What caused the Microsoft global outage in November 2026?
Microsoft identified unexpected server unavailability and infrastructure-related problems that contributed to connectivity issues. The company was investigating the underlying cause and had not released its complete post-incident findings.
2. Which Microsoft services were affected?
The disruption affected Outlook, Microsoft Teams, Microsoft 365, OneDrive, OneNote and Copilot. The impact varied depending on the service, feature and region.
3. Was the Microsoft outage caused by a cyberattack?
Microsoft said it was not aware of malicious activity causing the incident. Its investigation focused on infrastructure and server-related problems.
4. Did the Microsoft outage affect India?
Yes. Users in India reported problems accessing Microsoft services. IndiGo also confirmed that its email support services were affected and advised customers to use alternative support channels.
5. When will Microsoft services return to normal?
Microsoft reported improvements in server stability and recovery efforts on November 13, 2026. However, service capacity remained below normal levels, and the company had not confirmed a complete restoration time.
6. Why did the Microsoft outage affect businesses worldwide?
Many organizations depend on Microsoft’s cloud-based services for email, document management, meetings and daily operations. When shared infrastructure experiences problems, multiple businesses and industries can be affected simultaneously.
7. Is it safe to use Outlook during the outage?
Users can continue checking Outlook when the service is available. However, they should expect possible access problems or delayed messages and use alternative communication channels for urgent matters.
8. What should businesses do during a Microsoft outage?
Businesses should use alternative communication channels, maintain access to essential backups, inform customers about disruptions and follow their business continuity plans.
9. Did Microsoft Teams stop working completely?
No. Not every Teams feature was affected equally. Microsoft reported that some core communication functions remained available, while calendar-related activities experienced problems.
10. Will Microsoft publish a report explaining the outage?
Microsoft said it would provide a post-incident report after mitigation, including details about the root cause and measures intended to prevent similar problems.
About the Author